Which six vacuum checks does a PostgreSQL health check need?
Six: dead tuple ratio per table, whether autovacuum is actually running, transaction ID age, MultiXact age, anything holding back the vacuum horizon, and autovacuum worker saturation. The first four are the ones people check; the last two explain why vacuum can run constantly and still remove nothing.
Key facts
| Fact | Value | |---|---| | Autovacuum trigger | autovacuum_vacuum_threshold (50) + autovacuum_vacuum_scale_factor (0.2) × reltuples (docs) | | Wraparound limit | 2³¹ ≈ 2.1 billion transactions; autovacuum_freeze_max_age defaults to 200,000,000 (docs) | | Emergency failsafe | vacuum_failsafe_age default 1,600,000,000; PG14+ skips index cleanup and cost delays past it (docs) | | Default workers | autovacuum_max_workers = 3, autovacuum_vacuum_cost_limit = -1 (inherits vacuum_cost_limit 200), autovacuum_vacuum_cost_delay = 2ms (docs) | | Dead tuple thresholds we use | warning above 25% dead, critical above 50% of live rows | | Fleet observation | Across 50 monitored instances, 26% fail the dead-tuple-ratio check and 6% have tables autovacuum has fallen behind on |
Why this happens
PostgreSQL never updates a row in place. An UPDATE writes a new row version and leaves the old one on the page; a DELETE only marks the old version dead. Those dead versions stay visible to transactions old enough to need them, and only VACUUM reclaims the space once no snapshot can see them (routine vacuuming).
Vacuum has a second, unrelated job: freezing. Transaction IDs are 32-bit and wrap around, so every row version's insert XID has to be marked frozen before the cluster burns through 2³¹ transactions, or the database shuts down to protect itself (wraparound). Space reclamation is a performance problem. Freezing is an availability problem. A health check has to cover both, and they fail for different reasons.
Autovacuum handles both automatically, which is why most people never think about it — until one of six specific things stops it working. That is what the checks below are for.
How to detect it
1. Dead tuple ratio per table
SELECT schemaname, relname, n_live_tup, n_dead_tup,
       round(100.0 * n_dead_tup / NULLIF(n_live_tup + n_dead_tup, 0), 1) AS pct_dead
FROM pg_stat_user_tables
WHERE n_dead_tup > 1000
ORDER BY pct_dead DESC NULLS LAST
LIMIT 20;
pg_stat_user_tables tracks estimated live and dead row counts per table (docs). Sort by ratio, not by count. A 50-million-row table with 2 million dead tuples is 4% dead and perfectly normal; a 4,000-row queue table with 3,000 dead tuples is 43% dead and every sequential scan is reading mostly garbage. The raw count puts the big table at the top of your list and hides the one that is actually hurting.
Threshold: warn above 25% dead, alarm above 50%. Autovacuum's default 0.2 scale factor means a healthy table sawtooths up to roughly 17% dead and back, so anything sustained above 25% means the cycle is not completing. Prevents: slow sequential scans, index bloat, and the table growth covered in table bloat and dead tuples.
2. Is autovacuum actually running?
SELECT relname, n_dead_tup, autovacuum_count,
       last_autovacuum, last_autoanalyze
FROM pg_stat_user_tables
WHERE n_dead_tup > 10000
ORDER BY last_autovacuum ASC NULLS FIRST
LIMIT 20;
NULLS FIRST puts the tables that have never been autovacuumed at the top, which is the finding that matters most. A NULL last_autovacuum on a table with meaningful churn means either autovacuum is off, a per-table autovacuum_enabled = false storage parameter was set and forgotten, or the table has never crossed its threshold.
That last case is the scale-factor trap. Autovacuum triggers at autovacuum_vacuum_threshold + autovacuum_vacuum_scale_factor * reltuples (docs). With the default 0.2, a one-billion-row table waits for 200 million dead rows before autovacuum touches it. The proportional default is sensible for small tables and actively harmful for large ones — the bigger the table, the longer it is allowed to rot, and the more expensive the eventual vacuum.
Threshold: more than 3 tables with stale or absent autovacuum is a warning; more than 10 is worth treating as an incident. Prevents: a table quietly accumulating months of dead rows while the dashboard shows autovacuum running fine elsewhere.
3. Transaction ID age
-- per database
SELECT datname, age(datfrozenxid) AS xid_age,
       round(100.0 * age(datfrozenxid) / 2147483648, 1) AS pct_of_limit
FROM pg_database ORDER BY xid_age DESC;

-- per table, the one holding the database back
SELECT c.relname, age(c.relfrozenxid) AS xid_age
FROM pg_class c JOIN pg_namespace n ON n.oid = c.relnamespace
WHERE c.relkind IN ('r','m','t') AND n.nspname NOT IN ('pg_catalog','information_schema')
ORDER BY xid_age DESC LIMIT 20;
age(relfrozenxid) is how many transactions have elapsed since the oldest unfrozen row version in that relation (docs). The database age is just the maximum across its tables, so the per-table query tells you which one to fix.
Threshold: crossing autovacuum_freeze_max_age (200 million by default) is not an emergency — it is the soft trigger, and healthy databases oscillate around roughly 9% of the real limit forever. The genuine alarm is proportion of 2³¹: above 50% investigate, above 75% treat as urgent, and past vacuum_failsafe_age (1.6 billion, PG14+) PostgreSQL itself abandons index cleanup and ignores cost delays to catch up (docs). Prevents: the forced shutdown described in XID wraparound prevention.
4. MultiXact age
SELECT datname, mxid_age(datminmxid) AS multixact_age
FROM pg_database ORDER BY multixact_age DESC;
MultiXacts record several transactions locking the same row — SELECT ... FOR SHARE, foreign key checks, and similar. They have their own 32-bit counter, their own autovacuum_multixact_freeze_max_age (400 million by default), and they wrap independently of transaction IDs (docs). A workload heavy on row-level share locks can age MultiXacts far faster than XIDs, so a database that looks fine on check 3 can still be in trouble here. Most health checks skip this one entirely.
Threshold: same proportional reading as XID age — percentage of 2³¹, not percentage of the freeze setting. Prevents: a wraparound emergency on a counter nobody was watching.
5. What is holding the vacuum horizon back
SELECT pid, backend_xmin, age(backend_xmin) AS xmin_age, state,
       now() - xact_start AS txn_duration, left(query, 60) AS query
FROM pg_stat_activity
WHERE backend_xmin IS NOT NULL
ORDER BY age(backend_xmin) DESC LIMIT 10;

SELECT slot_name, slot_type, active, xmin, catalog_xmin,
       age(xmin) AS xmin_age
FROM pg_replication_slots ORDER BY age(xmin) DESC NULLS LAST;
This is the check that explains the confusing cases. Vacuum can only remove a row version older than the oldest snapshot any transaction might still need. One long-running transaction, one session idle in transaction, one prepared transaction, or one inactive replication slot pins that horizon (pg_stat_activity, pg_replication_slots). Autovacuum will keep running, keep logging, keep costing IO — and reclaim nothing. Dead tuples climb while every vacuum reports success.
An abandoned logical replication slot is the worst version of this, because it holds catalog_xmin back indefinitely with no session to kill and nothing on the activity view to notice.
Threshold: any backend_xmin age above a few million transactions, or any inactive slot at all, deserves an explanation. Prevents: chasing autovacuum settings for days when the cause is one session.
6. Worker saturation and cost limits
SELECT count(*) AS running_autovacuums,
       current_setting('autovacuum_max_workers') AS max_workers
FROM pg_stat_activity WHERE query LIKE 'autovacuum:%';

SELECT name, setting FROM pg_settings
WHERE name IN ('autovacuum_max_workers','autovacuum_vacuum_cost_limit',
               'autovacuum_vacuum_cost_delay','autovacuum_naptime');
Three workers by default (docs). If all three are occupied for hours on three enormous tables, every small, hot, high-churn table behind them waits. The cost limit is shared out across active workers, so raising autovacuum_max_workers without raising autovacuum_vacuum_cost_limit gives each worker a smaller budget and can make throughput worse.
Threshold: workers at maximum for a sustained period, or a cost limit still at the 200 default on hardware that can do far more IO. Prevents: the starvation pattern where the tables that need vacuum most are the ones that never get a worker. Autovacuum tuning covers the per-table settings that break the deadlock.
How MyDBA shows this
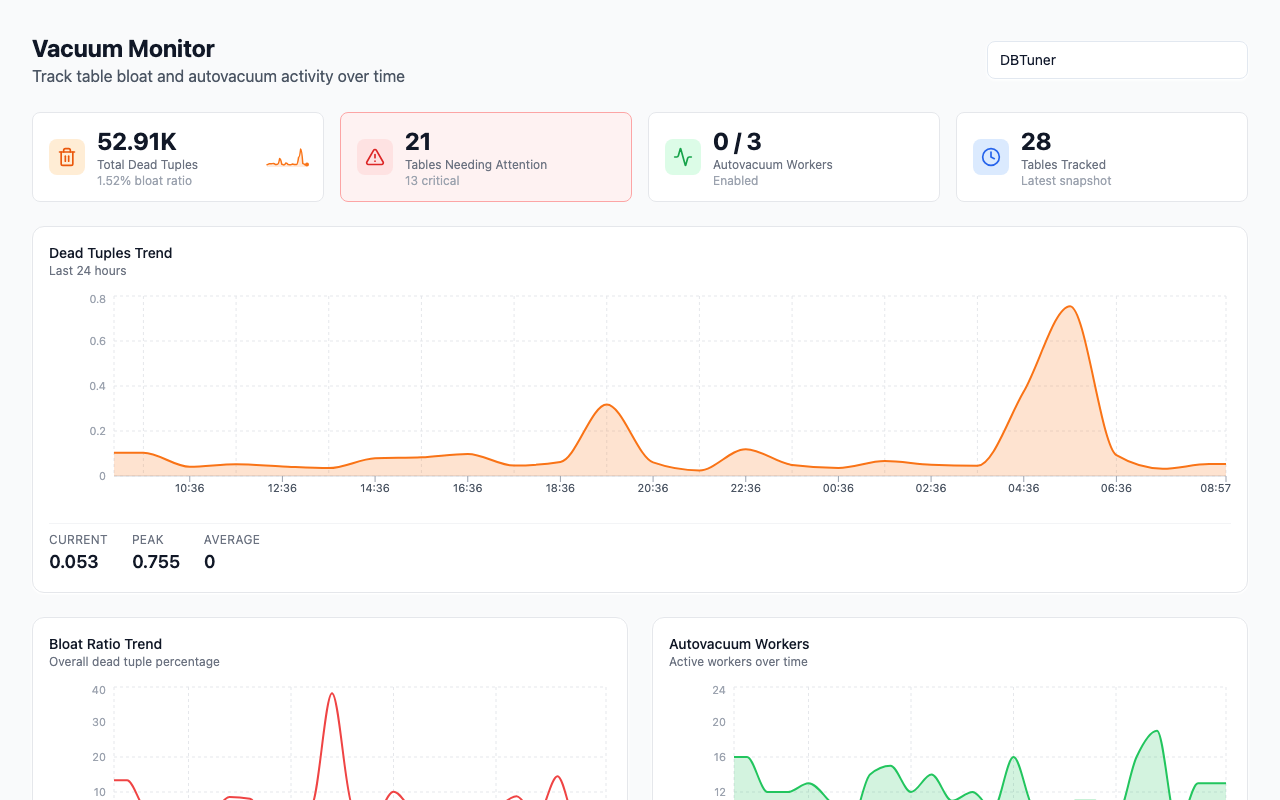
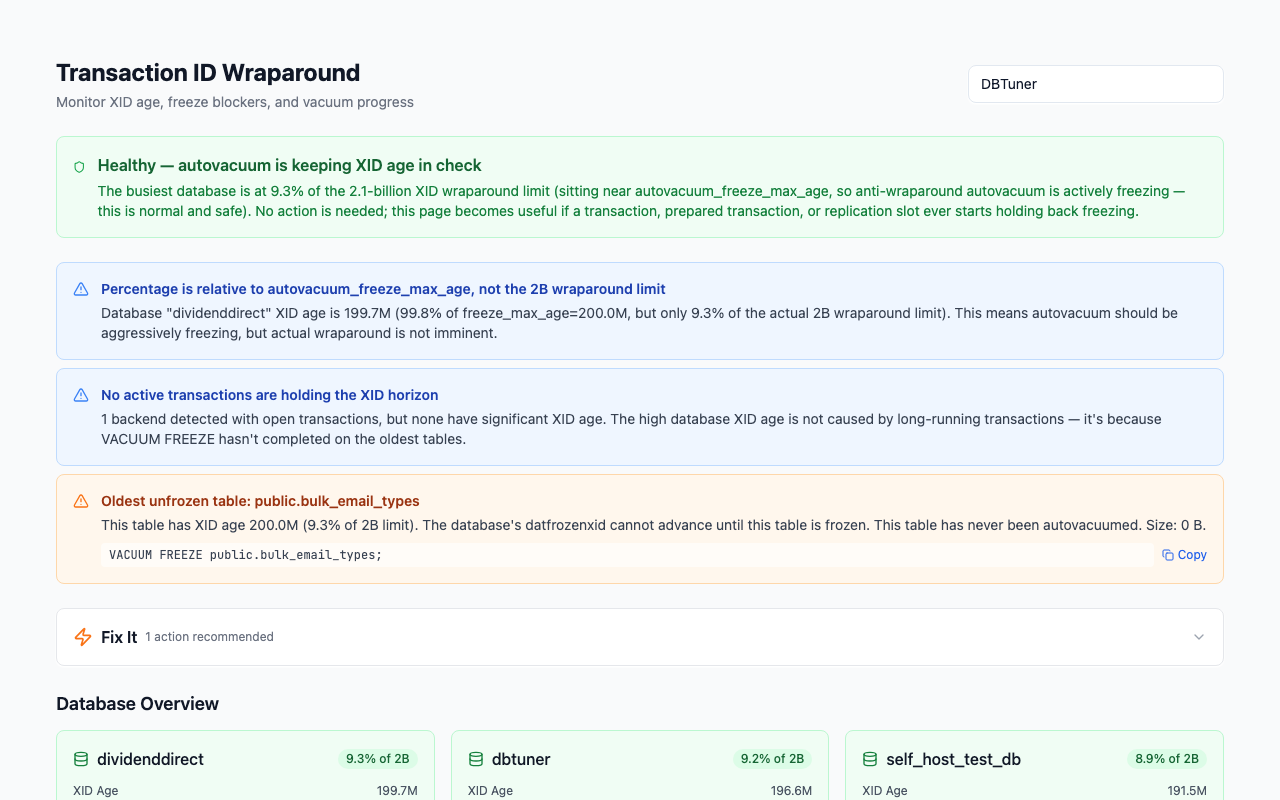
MyDBA scores these as its vacuum health domain — dead-tuple ratio, stale autovacuum, XID wraparound and long-running vacuums — and grades XID age against the 2³¹ limit rather than against autovacuum_freeze_max_age, which is why a database sitting normally above the freeze setting is not reported as critical. The XID and capacity runway view adds a trajectory: transactions consumed per day and estimated days of headroom, alongside the specific tables and blockers holding the horizon back. Across the 50 instances currently feeding these aggregates, 26% fail the dead-tuple-ratio check and 6% have tables autovacuum has fallen behind on, while 0% are failing the XID wraparound check — wraparound is rare, and expensive precisely because it is rare. You can see the same domain against your own database with a free PostgreSQL health check.
How to fix it
1. Find the blocker before changing settings. Run check 5. If a session or slot is pinning backend_xmin, terminate the session (SELECT pg_terminate_backend(pid)) or drop the slot (SELECT pg_drop_replication_slot('name')). No autovacuum setting fixes this. 2. Vacuum the worst table manually, so you can watch it: VACUUM (VERBOSE, ANALYZE) schema.table;. Check pg_stat_progress_vacuum while it runs. 3. Lower the scale factor on large tables individually rather than globally: ALTER TABLE big_table SET (autovacuum_vacuum_scale_factor = 0.01, autovacuum_vacuum_threshold = 10000);. 4. Raise the IO budget if vacuum is simply too slow: ALTER SYSTEM SET autovacuum_vacuum_cost_limit = 1000; then SELECT pg_reload_conf();. Raise workers only alongside the cost limit. 5. Re-enable anything disabled. SELECT relname, reloptions FROM pg_class WHERE reloptions::text LIKE '%autovacuum_enabled=false%';. 6. Avoid VACUUM FULL. It takes an ACCESS EXCLUSIVE lock and rewrites the whole table, blocking all reads and writes and needing space for a second copy (docs). It is almost never the answer — plain vacuum returns the space for reuse, and pg_repack rewrites without the exclusive lock if the file size genuinely has to come down.
How to prevent it
Set per-table autovacuum parameters when a table crosses roughly 50 million rows, rather than waiting for it to show up as bloat. Alert on dead tuple ratio, not count. Alert on XID and MultiXact age as a percentage of 2³¹, with the first alert well before the failsafe. Alert on inactive replication slots and on transactions older than an hour, because those are the two conditions that silently disable vacuum's usefulness while every other metric looks healthy. Set idle_in_transaction_session_timeout so abandoned sessions cannot hold the horizon forever. And read the vacuum checks together with the rest of the PostgreSQL health check checklist — bloat, index health and query latency all trace back here.
FAQ
How often should autovacuum run on a busy table?
Often enough that dead tuples never sustain above about 20% of live rows. For a high-churn table that usually means several times an hour, which the default 0.2 scale factor will not produce — set autovacuum_vacuum_scale_factor to 0.01–0.05 on that table specifically.
Does VACUUM return disk space to the operating system?
Usually not. Plain VACUUM marks space reusable inside the existing files, so the table stops growing but does not shrink. Only VACUUM FULL or pg_repack shrink files on disk, and truncation of trailing empty pages happens opportunistically. Reusable space is the normal, desirable outcome.
Why are my dead tuples climbing even though autovacuum keeps running?
Almost always something is holding the vacuum horizon back — a long transaction, an idle-in-transaction session, a prepared transaction, or a replication slot. Run check 5. Vacuum genuinely runs and genuinely removes nothing, because every dead row version is still potentially visible.
Is crossing autovacuum_freeze_max_age an emergency?
No. It is the soft trigger that tells autovacuum to start an anti-wraparound vacuum, and healthy databases sit above it routinely — 200 million is under 10% of the 2³¹ limit. Grade on proportion of 2³¹ instead, and treat vacuum_failsafe_age (1.6 billion) as the point where PostgreSQL has started taking emergency measures itself.
Part of the The PostgreSQL health check checklist guide. Last verified against PostgreSQL 18, 2026-09-17.