How do I back up a PostgreSQL database?
Use pg_dump -Fc for a single database you want to move or keep as a logical copy, pg_basebackup -X stream for a byte-level copy of the whole cluster, and WAL archiving on top of that base backup when you need point-in-time recovery. A backup you have never restored is an assumption, not a backup.
Key facts
| Fact | Value | |---|---| | Logical backup, one database | pg_dump; custom format -Fc (compressed, restorable selectively), directory format -Fd is the only one that supports parallel -j (docs) | | What pg_dump never captures | Roles, tablespace definitions, and every other database in the cluster — those come from pg_dumpall --globals-only (docs) | | Physical backup, whole cluster | pg_basebackup -X stream, run by a role with the REPLICATION attribute or pg_read_all_data-class rights (docs) | | Point-in-time recovery needs | wal_level = replica or higher, archive_mode = on, and archive_command or archive_library (docs) | | Archiver health view | pg_stat_archiver — archived_count, failed_count, last_failed_time (docs) | | Incremental base backups | pg_basebackup --incremental since PostgreSQL 17, requires summarize_wal = on; reassemble with pg_combinebackup (docs) | | Backup integrity check | pg_verifybackup validates a base backup's manifest before you need it (docs) | | Fleet observation | Across 50 monitored instances, 0% fail the archiver-health check — see the caveat below |
Why this happens
PostgreSQL gives you two fundamentally different kinds of backup, and most outages that turn into data loss come from someone assuming they had the other one.
A logical backup is a description of your data: pg_dump connects as an ordinary client, takes a consistent snapshot using a repeatable-read transaction, and writes out the SQL or an archive format that reproduces the objects (docs). It is portable across major versions and architectures, it can restore a single table, and it is slow to produce and slower to restore at any real size, because every index is rebuilt from scratch.
A physical backup is a copy of the files: pg_basebackup connects on the replication protocol and streams the data directory (docs). It is tied to the same major version and platform, it restores at the speed of your disk, and it restores the whole cluster — you cannot pull one table out of it.
The gap that surprises people is scope. pg_dump dumps one database. Roles, passwords, tablespace definitions and cluster-wide settings live outside any single database, so they are not in the file. pg_dumpall --globals-only is the piece that captures them (docs), and it is the piece people discover is missing at 3am when the restore comes up with no application user.
The second gap is time. A dump or a base backup is a single point. Everything written after it is gone unless the write-ahead log that followed it was archived. Continuous archiving plus a base backup is what makes recovery to an arbitrary moment possible, and it is the only mechanism in core PostgreSQL that does (docs). We covered the recovery half of that in PostgreSQL point-in-time recovery.
Archiving also creates its own failure mode. If archive_command starts failing — full destination, expired credentials, a network path that changed — PostgreSQL will not recycle the WAL segments it has not archived. pg_wal grows until the filesystem fills and the instance stops accepting writes. The same is true of an abandoned replication slot, which is why slot retention belongs in a backup review rather than only a replication one; see PostgreSQL replication slots.
How to detect it
Four queries tell you what your backup position actually is, as opposed to what the runbook says it is.
-- 1. Is archiving even on, and at what WAL level?
SELECT name, setting
FROM pg_settings
WHERE name IN ('wal_level', 'archive_mode', 'archive_command',
               'archive_library', 'summarize_wal');
archive_mode = off means you have no point-in-time recovery, whatever else is scheduled. Changing archive_mode requires a restart; archive_command only needs a reload.
-- 2. Is the archiver succeeding, and how recently?
SELECT archived_count,
       last_archived_wal,
       last_archived_time,
       failed_count,
       last_failed_wal,
       last_failed_time,
       stats_reset
FROM pg_stat_archiver;
Read failed_count as a lifetime counter since stats_reset. A non-zero value from eight months ago is history; a last_failed_time from four minutes ago is an incident. The number that matters most is the age of last_archived_time — if it is older than your RPO, your RPO is already blown.
-- 3. How much WAL is sitting on disk waiting?
SELECT count(*) AS segments,
       pg_size_pretty(sum(size)) AS pg_wal_size
FROM pg_ls_waldir();
Compare that against max_wal_size. Persistently far above it means something — the archiver or a slot — is pinning segments.
-- 4. Which replication slots are holding WAL back?
SELECT slot_name, slot_type, active, wal_status,
       pg_size_pretty(pg_wal_lsn_diff(pg_current_wal_lsn(), restart_lsn)) AS retained
FROM pg_replication_slots
ORDER BY pg_wal_lsn_diff(pg_current_wal_lsn(), restart_lsn) DESC;
wal_status of extended or lost is the warning; active = false with gigabytes retained is a slot nobody is using and nobody has dropped (docs).
How MyDBA shows this
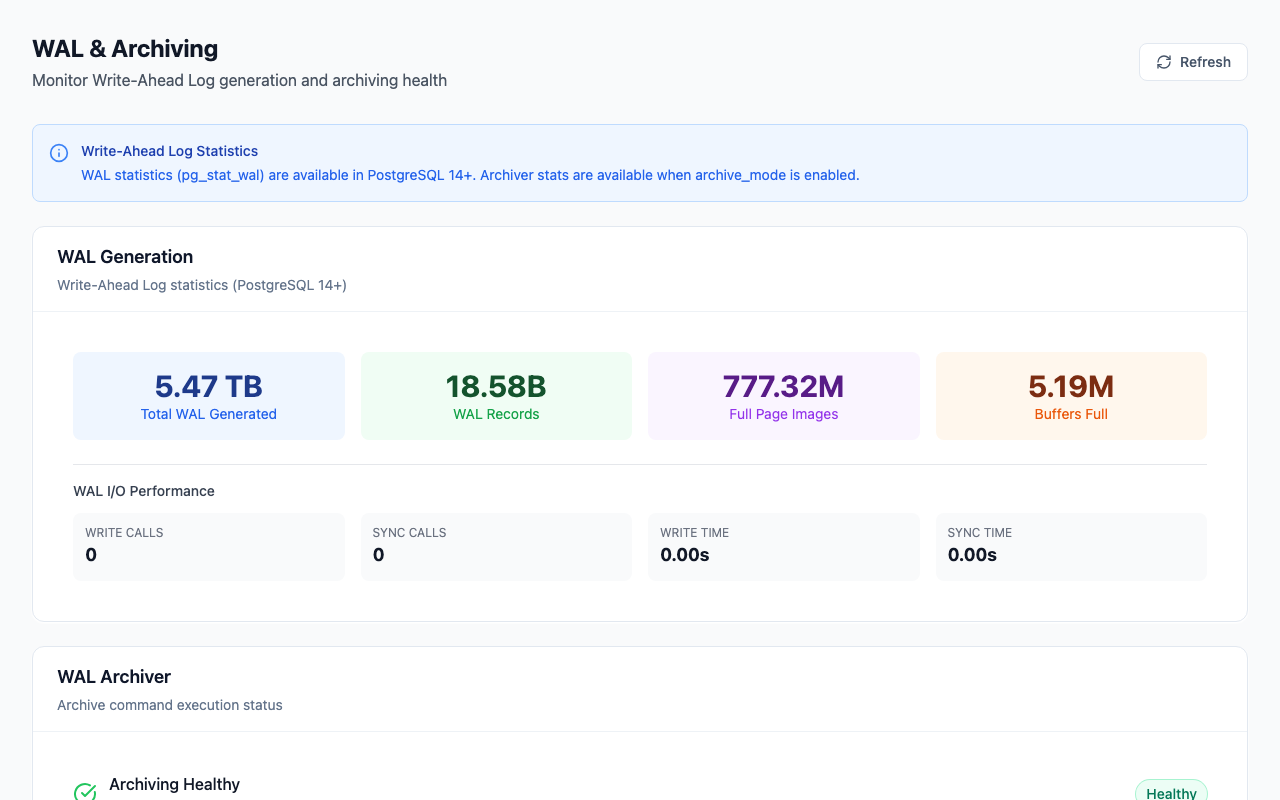
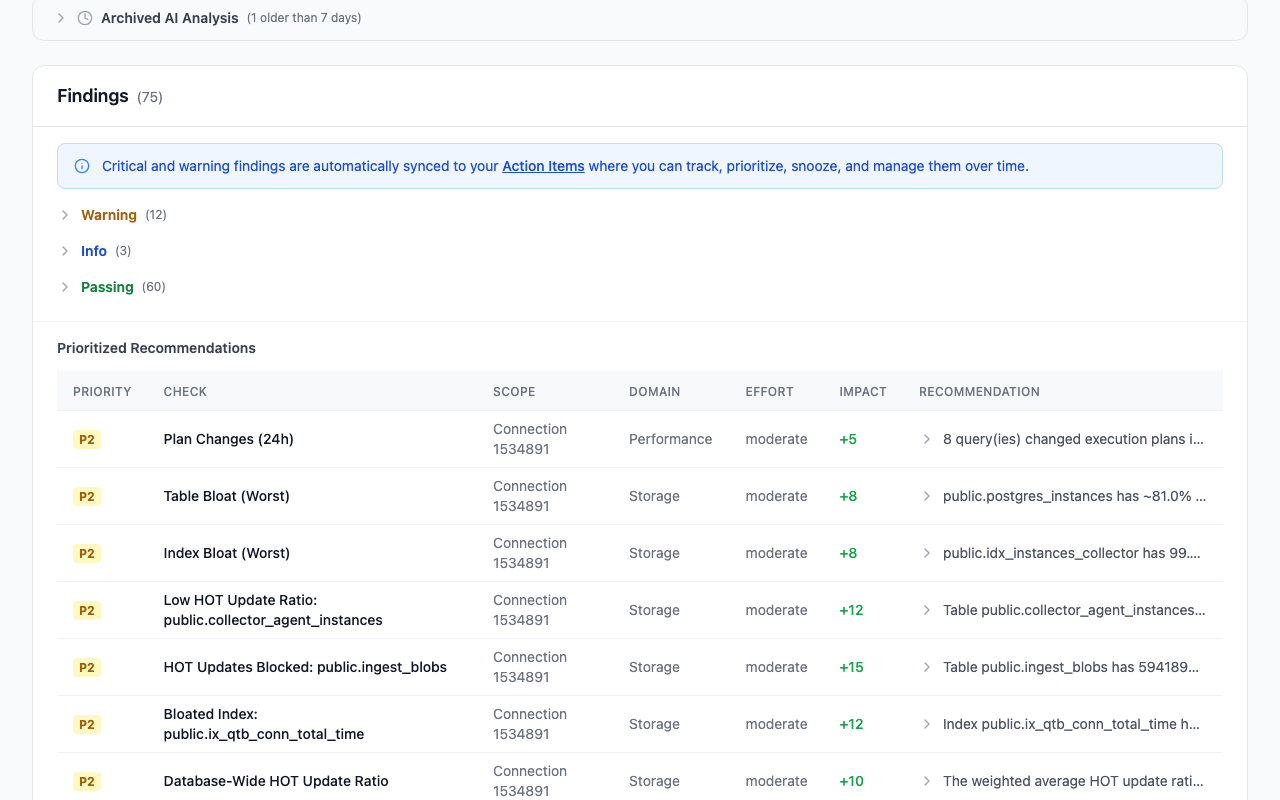
MyDBA scores a WAL & Backup health domain continuously rather than on demand: J1 reads archiver health from pg_stat_archiver snapshots, J2 the minutes since the last successful archive (warning past 30, critical past 120), J3 archive failures as a windowed delta rather than the lifetime counter, and J4 WAL buffers filling per hour; the WAL & Archiving page shows the generation rate, pg_wal size and archiver status behind those scores. Across 50 monitored instances, 0% currently fail J1 — but that figure needs its caveat stated plainly: J1 scores an instance with no archiver data as informational, not as a failure, so it measures archiver health where archiving is configured, not how many instances archive at all. The same 50 instances show 0% failing the inactive-slot check, and J4 has 20 instances with enough data to score, also at 0%. If you want your own instances measured this way, the free PostgreSQL health check covers this domain on one connection.
How to fix it
1. Capture the globals. Whatever else you run, run this too, and keep it beside the dumps: ``bash pg_dumpall --globals-only --file=globals-$(date +%F).sql ` 2. Dump a single database in a restorable format. Custom format, compressed, selectively restorable: `bash pg_dump -Fc -Z6 -d appdb -f appdb-$(date +%F).dump ` For large databases, directory format is the one that parallelises: `bash pg_dump -Fd -j 8 -d appdb -f /backups/appdb-$(date +%F) pg_restore -j 8 -d appdb_restored /backups/appdb-2026-09-17 ` -j on restore is independent of -j on dump, and usually the bigger win (docs). 3. Take a physical base backup of the cluster. -X stream opens a second connection and streams the WAL generated during the backup, so the result is self-contained and restorable without an archive: `bash pg_basebackup -h db-host -U repl_user -D /backups/base-$(date +%F) \ -Ft -z -X stream -c fast -P ` repl_user needs the REPLICATION attribute. -c fast forces an immediate checkpoint instead of waiting for a spread one. 4. Verify it before you trust it. `bash pg_verifybackup /backups/base-2026-09-17 ` 5. Turn on archiving if you need recovery to a point in time. `ini wal_level = replica archive_mode = on archive_command = 'test ! -f /archive/%f && cp %p /archive/%f' ` That cp` command is the documentation's illustration, not a production answer — it does not fsync and it has no retention. Use it to prove the path works, then move to a tool. 6. Restore into a scratch instance and time it. This is the step that converts a backup into evidence. Restore last night's artefact onto a spare host, start it, run your application's five most important read queries, and write down how long the whole thing took.
How to prevent it
Pick a tool rather than a shell one-liner. Three are worth knowing:
- pgBackRest — parallel compression and transfer, incremental and differential backups, per-repository retention, and a
checkcommand designed to be run from cron. The strongest default choice for a self-managed cluster you care about. - Barman — Python, catalogue-first, comfortable managing many servers from one backup host, with both rsync and streaming modes. Good when the backup host is the unit of administration.
- WAL-G — a single Go binary that streams straight to object storage. Good when your infrastructure is disposable and S3-compatible storage is the durable layer.
All three replace archive_command with their own wal-push equivalent, which is the point: they handle retries, compression, encryption and retention that a cp never will.
If you are on a managed provider, read the retention limits before relying on them. Amazon RDS and Aurora automated backups are capped at a 35-day retention window, and deleting the instance deletes them unless you have taken a manual snapshot. Managed snapshots are a physical copy of the provider's storage; you generally cannot restore one into your own hardware, and you cannot restore a single table from one. A periodic pg_dump alongside the provider's snapshots is the usual answer to both problems.
Alert on archiver age, not archiver failure. A failed archive command retries, so failures are noisy. The signal that maps to your RPO is the age of last_archived_time. Alert when it exceeds, say, three times your target.
Watch pg_wal growth as a capacity line, not just a metric. A stuck archiver and a forgotten slot both end at a full filesystem and a read-only database. Tracking disk trajectory is the same discipline as PostgreSQL capacity runway.
Write down the two numbers honestly. RPO is how much data you accept losing — with nightly dumps only, it is up to 24 hours, regardless of what the policy claims. RTO is how long recovery takes, and you only know it from a timed restore. Re-measure after the database doubles in size; both numbers move with it.
FAQ
Is pg_dump safe to run against a live production database?
Yes. It runs as a normal client in a repeatable-read transaction and takes no exclusive locks on your data (docs). It does take an ACCESS SHARE lock on every table it dumps, which will queue behind — and then block — anything wanting ACCESS EXCLUSIVE, so a long dump running alongside a DDL migration can stall writes. It also adds I/O and can hold back vacuum by keeping a long transaction open.
Can I restore a pg_basebackup onto a different PostgreSQL major version?
No. A base backup is a file-level copy and is tied to the major version, and to the platform's block size and integer alignment. Cross-version moves need a logical route: pg_dump/pg_restore, pg_upgrade, or logical replication. Keeping a periodic logical dump is what gives you an escape hatch from a physical-only strategy.
How often should I take a base backup if I have WAL archiving?
Often enough that replaying the WAL since the last one fits inside your RTO. Recovery replays every archived segment from the base backup forward, so a weekly base backup on a busy cluster can mean hours of replay. Weekly full plus daily incremental is a common shape; pg_basebackup --incremental (PostgreSQL 17+) makes that cheap in core, with pg_combinebackup reassembling the chain (docs).
Do I still need backups if I have a streaming replica?
Yes. A replica protects against hardware failure, not against mistakes: a DELETE without a WHERE, a bad migration or a dropped table replicates to the standby in milliseconds. Recovering from that needs a backup plus WAL you can stop replaying at a chosen moment, which is exactly what point-in-time recovery is for.
Part of the The PostgreSQL health check checklist guide. Last verified against PostgreSQL 18, 2026-09-17.