Which PostgreSQL settings should a configuration audit check?
A configuration audit checks roughly twenty settings in six groups: memory (shared_buffers, work_mem, maintenance_work_mem, effective_cache_size, max_connections), WAL and durability, planner costs, autovacuum aggressiveness, logging and statistics, and safety timeouts. For each, the question is not "is it the recommended number" but "does the symptom this setting causes match what we are seeing".
Key facts
| Fact | Value | |---|---| | Default shared_buffers | 128MB, unchanged since 8.x — resource consumption docs | | Default work_mem | 4MB, allocated per sort or hash node, not per query — docs | | Default random_page_cost | 4.0, a value calibrated for spinning disks — planner cost docs | | Default max_wal_size | 1GB; checkpoints trigger on size or checkpoint_timeout (5min), whichever comes first — WAL docs | | log_checkpoints default | on since PostgreSQL 15 — logging docs | | Fleet: log_lock_waits off | 52.6% of 38 monitored instances (MyDBA check A7_log_lock_waits) | | Fleet: auto_explain absent | 86.0% of 50 monitored instances (MyDBA check C10_auto_explain) |
Why this happens
PostgreSQL ships with defaults chosen so the server starts on a small machine, not so it performs well on yours. shared_buffers and the other resource settings are deliberately conservative starting points, and postgresql.conf is read at startup, with many settings needing a reload or restart. Nothing prompts you to revisit them, so they survive hardware upgrades, version upgrades and data growth untouched.
The second reason is that a wrong value rarely produces an error. It produces a symptom that looks like something else: a low work_mem looks like slow queries, a small max_wal_size looks like periodic I/O stalls, an unset statement_timeout looks like a connection leak. This is why "copy these values" is the wrong frame for an audit. The useful question is which of your current symptoms a setting could explain.
Memory
shared_buffers is PostgreSQL's own page cache; the 128MB default means almost every read goes to the operating system. A wrong value shows up as a low buffer cache hit ratio in pg_stat_database and heavy read I/O for a working set that would fit in RAM.
work_mem is the one most often misread. It is the limit for each sort, hash join or hash aggregate node in a plan, not a per-query budget, so a single query with several such nodes across several parallel workers can use a multiple of it (docs). Too low and sorts spill to disk — visible as growing temp_files and temp_bytes in pg_stat_database, and as external merge Disk: lines in EXPLAIN (ANALYZE, BUFFERS). Too high, multiplied across concurrent backends, is how an instance meets the OOM killer.
maintenance_work_mem governs VACUUM, CREATE INDEX and ALTER TABLE (docs). Left at 64MB on a large table, vacuum makes repeated index passes instead of one; the symptom is a vacuum that never seems to finish.
effective_cache_size allocates no memory at all. It is the planner's estimate of how much of the table is likely already cached, and a low value biases the planner away from index scans (docs). The symptom is sequential scans where an index exists and would be faster.
max_connections belongs in the memory group because it is a multiplier: each connection is a backend process with its own work areas, so raising it raises the worst-case footprint of every other setting here. Thousands of clients are a pooler's job, not this setting's — see max_connections and memory.
Durability and WAL
wal_level decides what is possible later: the replica default supports physical replication and PITR, while logical is required for logical replication and cannot be changed without a restart (docs). Discovering you need logical mid-incident means a restart mid-incident.
max_wal_size and checkpoint_timeout together set how often checkpoints run. Checkpoints that fire because WAL filled up rather than because the timeout elapsed are logged as checkpoints_req, and PostgreSQL will warn in the log that checkpoints are occurring too frequently (docs). The outside symptom is a regular I/O spike and latency wobble on a fixed-ish cadence. checkpoint_completion_target (default 0.9 since PostgreSQL 14) spreads that write over the interval rather than concentrating it.
synchronous_commit is a durability decision, not a performance knob to turn casually: off lets commits return before the WAL is flushed, risking a small window of recent transactions on a crash (docs). archive_mode is off by default, which means no WAL archive, which means no point-in-time recovery — a setting whose wrong value has no symptom at all until the day you need it.
Planner
random_page_cost defaults to 4.0, four times seq_page_cost. On SSD or NVMe storage that ratio is wrong, and the documentation notes that reducing it is appropriate where the data is likely cached or the storage has low random-access cost (docs). The symptom is the same as a low effective_cache_size: sequential scans chosen over usable indexes.
effective_io_concurrency tells PostgreSQL how many concurrent I/O requests the storage can handle (docs). default_statistics_target (default 100) sets sample size for ANALYZE; on columns with skewed distributions, too small a sample produces row estimates off by orders of magnitude, and the symptom is a plan with a nested loop where a hash join was needed (docs). jit is on by default and helps long analytical queries; on short OLTP queries the compilation cost can exceed the query, and the symptom is a plan whose JIT timing section is a large fraction of total time (docs).
Autovacuum
Autovacuum's defaults are deliberately gentle. autovacuum_vacuum_cost_limit throttles how much work a vacuum does before sleeping autovacuum_vacuum_cost_delay (docs). On a busy instance the symptom of too-low a limit is dead tuples accumulating faster than they are reclaimed — table bloat, and eventually transaction-ID age.
The scale factors are the other trap. autovacuum_vacuum_scale_factor defaults to 0.2, meaning a table is vacuumed after 20% of its rows change. On a 500-million-row table that is 100 million dead tuples before anything happens. The fix is a per-table ALTER TABLE ... SET (autovacuum_vacuum_scale_factor = ...), not a global change. autovacuum_naptime (1min) sets how often the launcher checks; the vacuum health checks cover what to watch.
Observability
These settings have no performance symptom; their wrong value costs you the next incident's diagnosis.
log_min_duration_statement is -1 (nothing logged) by default (docs). log_lock_waits is off by default and logs when a session waits longer than deadlock_timeout for a lock — the cheapest way to see lock contention after the fact. log_checkpoints has defaulted to on since PostgreSQL 15, so an instance with it off was configured on an older version and carried forward.
track_io_timing is off by default; without it, pg_stat_statements and EXPLAIN (ANALYZE, BUFFERS) cannot tell you how much of a query's time was I/O (docs). And pg_stat_statements itself must be in shared_preload_libraries, which requires a restart (docs) — so if it is missing, you have no query-level history at all until the next maintenance window.
Across the instances MyDBA monitors, this group fails most: 52.6% of 38 instances have log_lock_waits off, 31.6% log_checkpoints off, 28.9% track_io_timing off, and 16.0% of 50 have no pg_stat_statements. The auto_explain figure is the starkest — 86.0% of 50 instances do not load it, so there is no automatic plan capture for the slow queries they do log.
Safety timeouts
statement_timeout, lock_timeout and idle_in_transaction_session_timeout all default to 0, meaning no limit (docs). The symptom of the third one is the most expensive: a session left idle in transaction holds its transaction open, which blocks vacuum from reclaiming dead tuples anywhere in the database and holds locks a migration is waiting on. Set them per role or per session where a global value would break a legitimate long report.
How to detect it
Start with what has actually been changed. This lists every setting that is not at its compiled-in default, with where the value came from:
SELECT name, setting, unit, source, sourcefile, sourceline
FROM pg_settings
WHERE source NOT IN ('default', 'override')
ORDER BY source, name;
source tells you whether a value came from configuration file, ALTER SYSTEM (postgresql.auto.conf), the command line, or a per-database/per-role ALTER ... SET — and an ALTER SYSTEM value silently overrides postgresql.conf (docs), which is how a "we changed that months ago" belief survives being wrong. A short list here on a busy production instance is itself the finding.
Then check the specific values against the instance's RAM:
SELECT name, setting, unit, boot_val, reset_val, pending_restart
FROM pg_settings
WHERE name IN ('shared_buffers','work_mem','maintenance_work_mem','effective_cache_size',
               'max_connections','wal_level','max_wal_size','checkpoint_timeout',
               'checkpoint_completion_target','synchronous_commit','archive_mode',
               'random_page_cost','effective_io_concurrency','default_statistics_target','jit',
               'autovacuum_vacuum_cost_limit','autovacuum_naptime','autovacuum_vacuum_scale_factor',
               'log_min_duration_statement','log_lock_waits','log_checkpoints','track_io_timing',
               'shared_preload_libraries','statement_timeout','lock_timeout',
               'idle_in_transaction_session_timeout')
ORDER BY name;
boot_val is the compiled default, reset_val the value a RESET returns to, and pending_restart is true when a restart-only setting was changed but the server never restarted — a value written down but not in effect.
For evidence rather than configuration, pg_stat_database supplies the symptoms: temp_files/temp_bytes for work_mem, blks_hit against blks_read for shared_buffers, and checkpoints_req against checkpoints_timed (in pg_stat_checkpointer on PostgreSQL 17+) for max_wal_size.
How MyDBA shows this
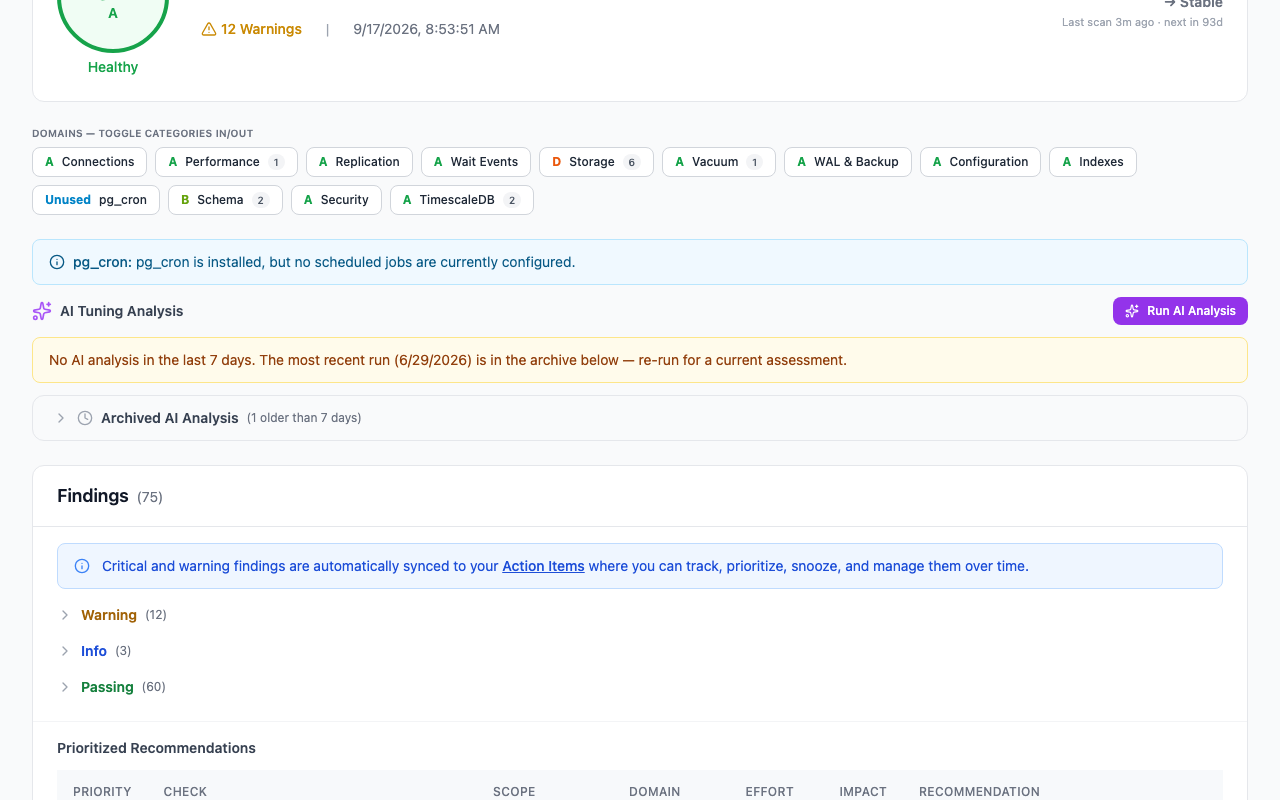
MyDBA's configuration domain runs its A1–A12 checks continuously rather than as a one-off scan, and scores the memory settings against the instance's actual RAM as reported by the collector rather than a fixed threshold — so shared_buffers at 2GB is a finding on a 64GB box and a pass on an 8GB one. The fleet figures above come from those same checks: A7_log_lock_waits failing on 52.6% of 38 instances, A9_pg_stat_statements on 16.0% of 50, A1_shared_buffers on 10.0% of 20. There is also a free, no-signup config tuner at /tools/config-tuner that takes your RAM, core count and workload shape and shows the values it would suggest, with the reasoning for each. To run the same checks against your own instance, the free PostgreSQL health check covers the configuration domain on one database.
How to fix it
1. Record the current state first. Save the output of the pg_settings query above; you will need it to answer "what did we change". 2. Fix the observability group first, because it costs nothing and makes everything after it measurable: ALTER SYSTEM SET log_lock_waits = on; ALTER SYSTEM SET track_io_timing = on; ALTER SYSTEM SET log_min_duration_statement = '1s'; then SELECT pg_reload_conf();. None of these need a restart. 3. Add pg_stat_statements if it is missing: ALTER SYSTEM SET shared_preload_libraries = 'pg_stat_statements'; then restart, then CREATE EXTENSION pg_stat_statements;. This is the only genuinely disruptive step, so batch it with anything else needing a restart (wal_level, max_connections). 4. Set the timeouts, per role where a global value would be too blunt: ALTER ROLE app_user SET statement_timeout = '30s'; ALTER ROLE app_user SET idle_in_transaction_session_timeout = '5min'; 5. Change memory settings one at a time, with a measurement in between. Raise work_mem only if temp_files is climbing, then re-check. 6. Verify each change landed: re-run the pg_settings query and confirm pending_restart is false and source is what you expect. An ALTER SYSTEM that was never reloaded is a change you believe you made.
The performance tuning guide covers the measurement side of that loop in more detail.
How to prevent it
Treat the configuration as code. Keep postgresql.conf and any ALTER SYSTEM values in version control, and re-run the non-default pg_settings query on a schedule so drift between the file and the running server is visible rather than discovered. pending_restart = true sitting unnoticed for months is a common find.
Re-audit after three specific events, because each one invalidates values that were correct before it: a hardware or instance-class change (every RAM-relative setting is now wrong), a major-version upgrade (defaults move — checkpoint_completion_target in 14, log_checkpoints in 15), and significant data growth (the 0.2 autovacuum scale factor that was fine at 5 million rows is not fine at 500 million). Watching table growth against that last one is what capacity runway is for. The full sequence of audits is in the PostgreSQL health check checklist.
FAQ
What should shared_buffers actually be set to?
The common starting point is 25% of RAM on a dedicated database server, then measure. It is a starting point rather than an answer because PostgreSQL also relies on the operating system's page cache, so very large values are not reliably better. Change it, watch the buffer cache hit ratio and read I/O over a representative week, and adjust.
Why is work_mem dangerous to raise?
Because the limit applies per sort or hash node, not per query. A plan with three hash joins under two parallel workers can allocate several times work_mem for one statement, and dozens of concurrent statements multiply that again. Raise it in small steps, or set it for a specific role or session that runs the heavy reports rather than globally.
Do I need a restart to change these?
Most are reloadable with SELECT pg_reload_conf(); — logging settings, timeouts, work_mem, planner costs, autovacuum thresholds. shared_buffers, max_connections, wal_level and shared_preload_libraries require a restart. pg_settings.context tells you which category a setting falls into, and pending_restart tells you whether one is already owed.
How often should a configuration audit run?
Quarterly is reasonable for a stable system, but the events matter more than the calendar: after any hardware change, any major-version upgrade, and any significant change in data volume or connection count. Continuous scoring removes the need to remember, which is why MyDBA re-scores the domain rather than offering a button to press.
Part of the The PostgreSQL health check checklist guide. Last verified against PostgreSQL 18, 2026-09-17.