What is a GiST index in PostgreSQL and when should you use it?
GiST (Generalised Search Tree) is not one index algorithm but a balanced-tree framework: each operator class supplies its own consistent, union, penalty and picksplit functions. You choose GiST when your data type or operator only works with it — geometry, ranges, trigram similarity, ltree, nearest-neighbour ordering and exclusion constraints — rather than for ordinary scalar columns.
Key facts
| Fact | Value | |---|---| | What GiST actually is | A balanced tree plus an extensibility interface; an operator class supplies consistent, union, penalty, picksplit and friends (gist-extensibility) | | Required support functions | 5 mandatory, plus optional compress, decompress, distance, options, sortsupport (docs) | | Lossy by design | GiST scans can return false positives, so PostgreSQL rechecks rows against the heap (indexes-types) | | Nearest-neighbour support | ORDER BY column <-> constant LIMIT k is answered by the index itself (indexes-ordering) | | Exclusion constraints | EXCLUDE USING gist (...) — GiST is the usual access method (ddl-constraints) | | Equality inside an exclusion constraint | Needs the btree_gist extension (btree-gist) | | Build tuning | buffering storage parameter: auto (default), on, off (sql-createindex) | | Fleet observation | Across 50 monitored instances, 44% have at least one index flagged as bloated (MyDBA B4_index_bloat, 2026-09-17) |
Why this happens
Most index questions have an answer of the form "B-tree, unless...". GiST is the "unless". A B-tree assumes a total order on the keys: every value is less than, equal to or greater than every other. That assumption is what makes <, = and > cheap, and it is exactly what a polygon, a time range or a trigram set does not have. There is no sensible way to say one bounding box is "less than" another.
GiST drops the ordering assumption and keeps only the tree. Each internal page holds a predicate that is true for everything below it — a bounding box, a union of ranges, a signature — and the search descends into any subtree whose predicate might match. The type-specific behaviour lives entirely in the operator class: union builds the parent predicate, consistent decides whether a subtree can be skipped, penalty and picksplit decide how entries are placed and how a full page is split (GiST extensibility).
That indirection is why extensions can add index support without patching PostgreSQL. PostGIS, pg_trgm, ltree, hstore, intarray and the built-in range and geometric types all ship operator classes rather than index code (built-in operator classes).
Two consequences follow directly from the design. First, GiST is lossy: consistent may answer "maybe", so the executor rechecks candidate rows against the heap (index types). You see this as Rows Removed by Index Recheck in EXPLAIN (ANALYZE, BUFFERS). Second, because an operator class can also supply a distance function, GiST can return rows in order of distance from a point — the nearest-neighbour ability B-tree and GIN do not have (ordering operators).
What people actually use it for
- Geometric and spatial data. The built-in
box,polygonandcircleclasses, and in practice PostGISgeometry/geography. See PostGIS spatial indexing for the operator classes that matter there. - Ranges and multiranges.
int4range,tstzrange,daterange— overlap (&&), containment (@>) and adjacency (-|-) (range type indexing). - Trigram similarity.
pg_trgmoffers bothgist_trgm_opsandgin_trgm_opsforLIKE '%foo%'and%similarity (pg_trgm). - Full-text search, as the smaller, slower-to-search alternative to GIN (text search indexes). Most people should still read full-text search with tsvector and GIN first.
ltreehierarchies (ltree).- Nearest neighbour:
ORDER BY location <-> point(...) LIMIT 10. - Exclusion constraints — the one case where no other access method will do.
How to detect it
Which access methods are in use, and what do they cost?
SELECT am.amname AS access_method,
       count(*) AS index_count,
       pg_size_pretty(sum(pg_relation_size(i.indexrelid))) AS total_size,
       sum(s.idx_scan) AS total_scans
FROM pg_index i
JOIN pg_class c ON c.oid = i.indexrelid
JOIN pg_am am ON am.oid = c.relam
LEFT JOIN pg_stat_user_indexes s ON s.indexrelid = i.indexrelid
GROUP BY am.amname
ORDER BY sum(pg_relation_size(i.indexrelid)) DESC;
Expect btree to dominate. A handful of gist rows with healthy total_scans is normal for a spatial or scheduling schema; gist rows with zero scans usually mean somebody indexed a scalar column with GiST because it looked clever.
To see the lossiness, run a query against a GiST index and read the recheck line:
EXPLAIN (ANALYZE, BUFFERS)
SELECT * FROM bookings WHERE during && tstzrange(now(), now() + interval '2 hours');
Bitmap Heap Scan on bookings (cost=... rows=...)
Recheck Cond: (during && ...)
Rows Removed by Index Recheck: 184
-> Bitmap Index Scan on bookings_during_gist (...)Rows Removed by Index Recheck is the price of the lossy predicate. A small number is expected. A large one means the index is answering "maybe" far too often — usually a bounding predicate that is a poor fit for the data (using EXPLAIN).
How MyDBA shows this
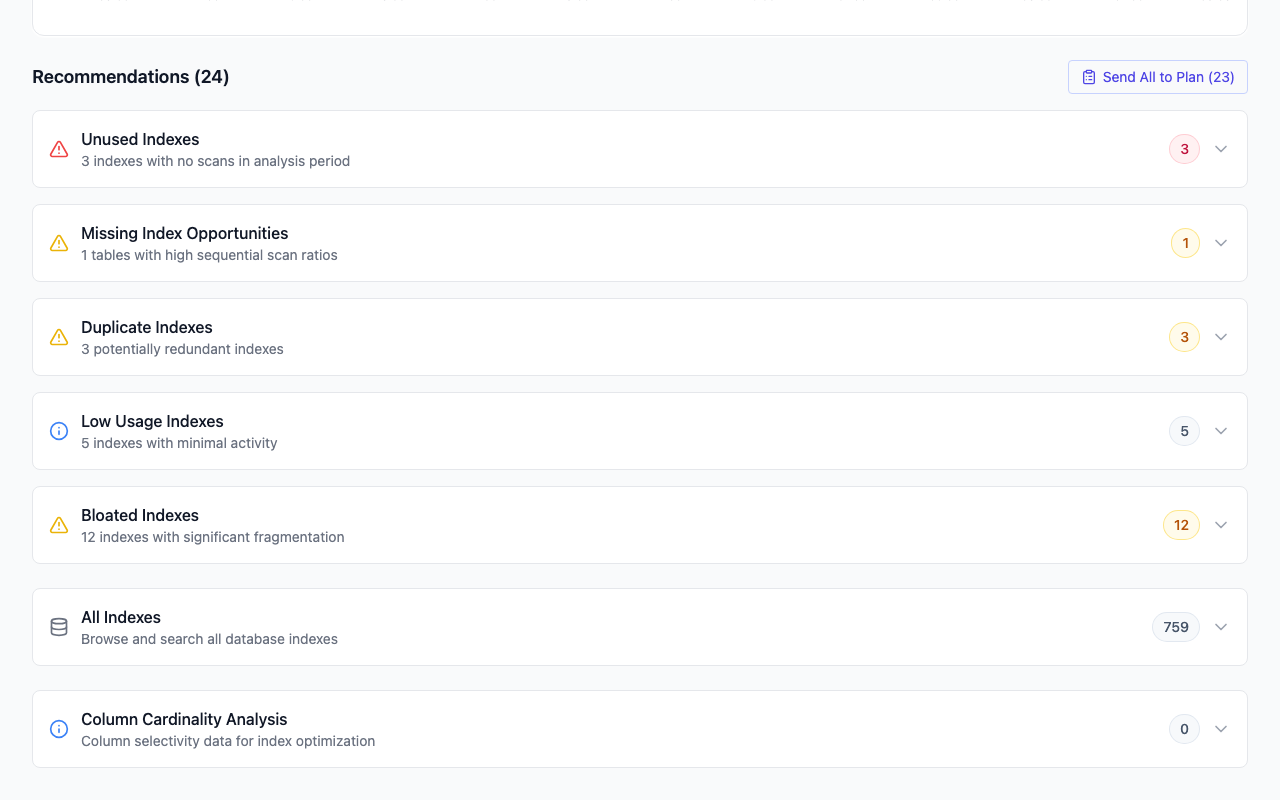
The index advisor's All Indexes list carries each index's access method, size and scan count in the same table, so a gist or gin entry sits next to the B-trees rather than hiding behind them — which is how you notice an unusual access method on a column that did not need one, or a GiST index with no scans at all. The Bloated Indexes card applies to GiST the same way it applies to B-tree; across 50 monitored instances, 44% have at least one index flagged as bloated. If the instance runs PostGIS, the PostGIS health domain (checks G0–G12) scores spatial index coverage alongside extension and library versions. You can see the same index list on your own database with a free PostgreSQL health check.
How to fix it
The worked example: a room that cannot be double-booked. Overlap is not equality, so a unique index cannot express it — an exclusion constraint can.
CREATE EXTENSION IF NOT EXISTS btree_gist;

CREATE TABLE room_bookings (
    booking_id   bigint GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
    room         text      NOT NULL,
    during       tstzrange NOT NULL,
    CONSTRAINT no_double_booking
        EXCLUDE USING gist (room WITH =, during WITH &&)
);
btree_gist is what lets the scalar room column participate with =; without it PostgreSQL has no GiST operator class for text equality (btree_gist). The constraint creates its own GiST index, so no separate CREATE INDEX is needed.
INSERT INTO room_bookings (room, during)
VALUES ('blue', tstzrange('2026-10-05 09:00Z', '2026-10-05 10:00Z'));

INSERT INTO room_bookings (room, during)
VALUES ('blue', tstzrange('2026-10-05 09:30Z', '2026-10-05 11:00Z'));
-- ERROR:  conflicting key value violates exclusion constraint "no_double_booking"
For the rest:
1. Adding GiST to an existing table — use CREATE INDEX CONCURRENTLY, as you would for any access method. See creating an index concurrently. 2. Large builds — leave buffering at auto; set it explicitly only if you have measured a difference (CREATE INDEX). 3. Choosing between GiST and GIN. GIN is faster to search and usually larger, and its updates are slower (mitigated by the pending list). GiST is smaller, faster to build, and is the only one of the two that supports KNN ordering and exclusion constraints. For text search the PostgreSQL docs put it plainly: GIN lookups are roughly three times faster, GIN builds roughly three times slower (text search indexes). The full comparison is in GIN indexes. 4. Consider SP-GiST — the non-balanced cousin, for naturally partitioned structures such as quadtrees, k-d trees and radix trees. It wins where the data clusters unevenly and GiST's bounding boxes overlap badly (SP-GiST).
How to prevent it
The practical rule is negative: you rarely choose GiST for a scalar column. You end up on GiST because the operator you need — &&, @>, <->, %, @@ — has no B-tree operator class. If your predicate is =, < or BETWEEN on an ordinary column, use a B-tree and move on (index types).
Three things worth watching:
- Unused GiST indexes. Across 31 monitored instances, 58% have at least one unused index. GiST indexes are cheap to build but not free to maintain.
- Recheck volume. Track
Rows Removed by Index Recheckon your hot spatial and range queries; a rise means the predicate has stopped discriminating. - Bloat. GiST pages split like any other and are covered by the same
REINDEX CONCURRENTLYremedy as B-tree — see when and how to REINDEX.
FAQ
Is GiST faster than a B-tree?
No, and it is not trying to be. For scalar equality and range predicates a B-tree is faster and smaller. GiST exists for operators a B-tree cannot answer at all. If both are possible, pick the B-tree.
Why does my GiST query show "Rows Removed by Index Recheck"?
Because GiST is lossy. The index stores an approximate predicate — typically a bounding box or a signature — so it returns candidates that PostgreSQL must verify against the heap (index types). A small recheck count is normal; a large one suggests a poor-fitting operator class or badly shaped data.
Do I need btree_gist for every exclusion constraint?
Only when a column in the constraint is compared with = and its type has no native GiST operator class — which is the case for text, int, uuid and most scalars. A constraint made only of range or geometric columns with && needs no extension (btree_gist).
Can GiST do index-only scans?
Some operator classes can, when they provide a fetch function that reconstructs the original value from the index entry. Many — including the compressed spatial classes — cannot, so plan for a heap fetch (index-only scans).
When should I pick SP-GiST over GiST?
When the data partitions naturally and non-uniformly — points clustered in cities, text with shared prefixes, non-overlapping ranges. SP-GiST's partitions never overlap, which avoids the repeated descents that hurt GiST on skewed data (SP-GiST).
Part of the PostgreSQL index types: the complete guide guide. Last verified against PostgreSQL 18, 2026-09-17.